Product Matcher
Schedule and history
Matching can run by itself, for example after each new scrape or every Monday at 06:00. Every run, by hand or by schedule, is in History with its status and its cost. Each scheduled run holds money in your wallet like a run you start by hand.
- Open your group, pick Matching, then Match the data. Open the 3-dots menu next to Run match and pick Run configuration.
- In Match settings, press Change next to Schedule. The Matching schedule dialog opens.
- Pick an Automation: Run once (no schedule), After each scrape, Daily, Every N days (set Run every (days)) or Weekly (pick days) (pick the days).
- For a calendar choice, set Time and Timezone.
- Read the cost line: each scheduled run reserves up to an amount, charged to the group owner’s wallet. When the balance is too low, that run is skipped.
- Press Save. With Run once, the button is Save and run and also starts a run now. Close leaves without saving.
- Open History to see every run, newest first. The run whose results you see has the Active chip. A waiting or running row has Stop.
- Read the columns: Run, Status, Sources compared, Items in scope, Matched, Your products matched, Waiting for review, Match rate, Pictures and Cost.
- Tick two rows and press Compare 2 runs to compare them. Show deleted runs also lists runs you deleted.
- The Danger zone below the table deletes matching data, or undoes all your review decisions with Unmatch all reviewed….
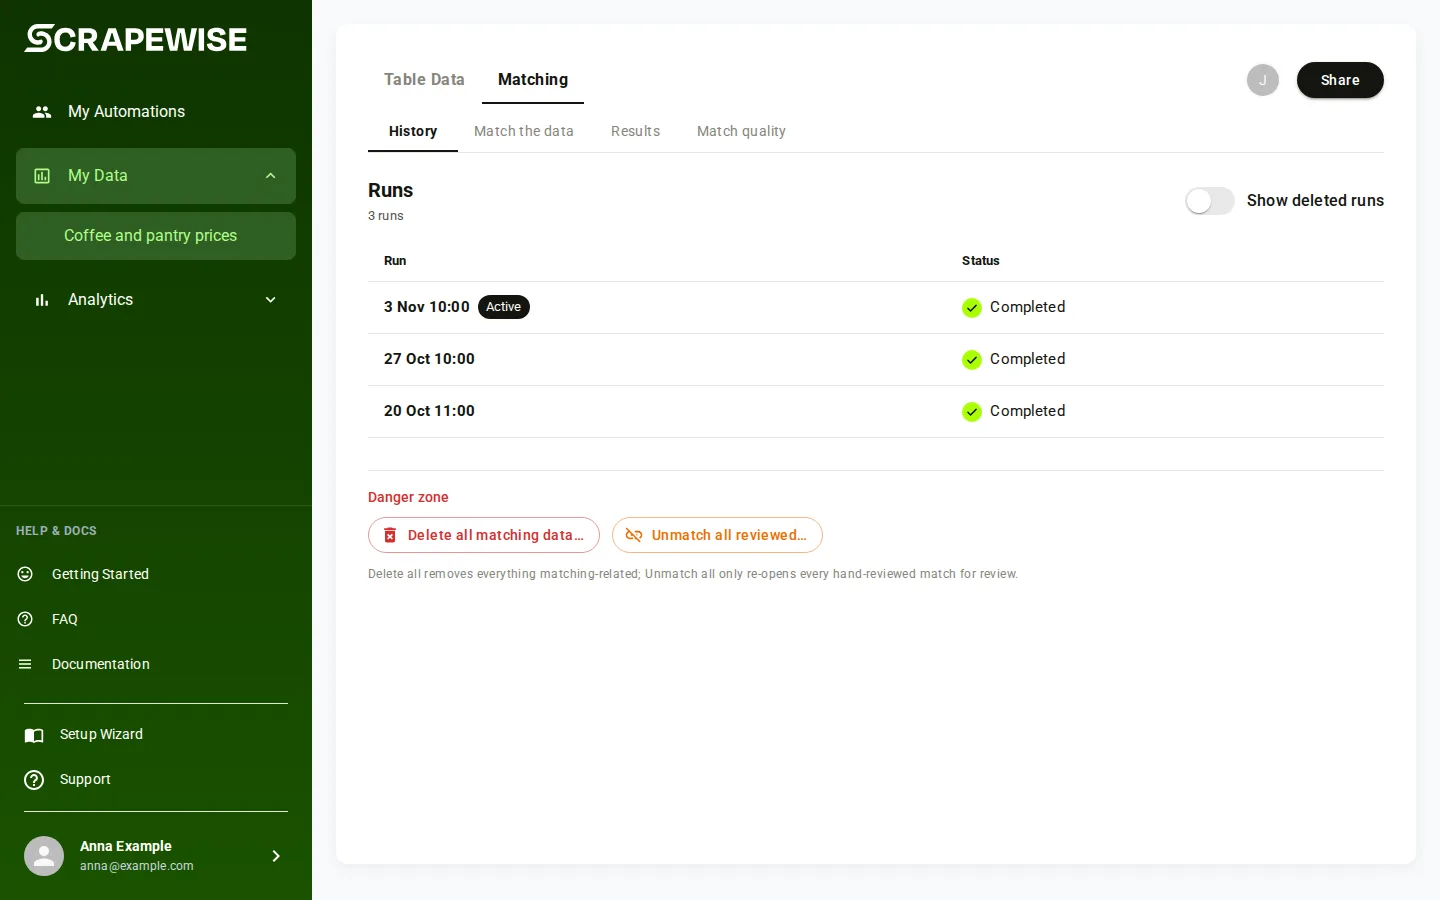
The Status column says Completed, Failed (the reason on hover), Stopped, Running, Queued or Draft. “Held” means the result looked wrong in size, so it was not delivered: “Held · N vs M rows · previous results kept”. A run skipped for a low wallet shows “Not started: balance too low” in Cost.
- Base address
https://portal.scrapewise.ai/api/scraper-api, headerAuthorization: Bearer <key>. Which key: a Read key looks, a Full key also changes things, see Read or Full. - With a Full key, set the schedule:
PATCH /api/scraper/group/{id}/match/schedulewith a newIdempotency-Keyheader. The PATCH never starts a run. - With a Full key, clear the schedule by sending the body
null. - With a Read key, read the schedule and the next run time:
GET /api/scraper/group/{id}/match(schedule,nextRunAt). - With a Read key, list the runs:
GET /api/scraper/group/{id}/match/history. AddwithDeleted=trueto see deleted runs too. - With a Read key, download the daily matched file, see the next section.
curl -X PATCH "https://portal.scrapewise.ai/api/scraper-api/api/scraper/group/[GROUP ID]/match/schedule" \
  -H "Authorization: Bearer $SCRAPEWISE_FULL_KEY" \
  -H "Idempotency-Key: [NEW UUID]" \
  -H "Content-Type: application/json" \
  -d '{ "type": "WEEKLY", "daysOfWeek": ["MONDAY"], "time": "06:00", "zone": "Europe/Tallinn" }'
type | Runs |
|---|---|
AFTER_SCRAPES | After each new scrape of the group |
DAILY | Every day at time |
EVERY_N_DAYS | Every intervalDays days (1 to 366) at time |
WEEKLY | On the daysOfWeek (at least one) at time |
time is HH:mm (24 h). zone is a time zone name, default Europe/Tallinn. A new schedule starts from now; missed earlier times are not run. The answer has schedule, nextRunAt and a new version.
- Connect your assistant with a Full key to change the schedule, or a Read key to read.
- Ask it to set the schedule, for example “match this group every Monday at 06:00 Tallinn time”. The tool is
scrapewise_update_matcher_schedule(Full) with a newidempotency_key. To stop automatic matching, it sends the bodynull. - Ask it when the next run is:
scrapewise_get_matcher_job(Read), fieldnextRunAt. - Ask it for the run history:
scrapewise_get_matcher_history(Read). - Ask it whether the daily matched file is ready:
scrapewise_get_matched_export_latest_status(Read). It gives the address to download it.
scrapewise_update_matcher_schedule
{
  "id": "[GROUP ID]",
  "idempotency_key": "[NEW UUID]",
  "body": { "type": "DAILY", "time": "06:00", "zone": "Europe/Tallinn" }
}
Daily matched file
One fixed address per group always gives the newest file of all matched rows, as gzip JSON Lines or CSV. Use it for a daily import. Read and Full keys both work.
curl -H "Authorization: Bearer $SCRAPEWISE_READ_KEY" -o matched.jsonl.gz \
  "https://portal.scrapewise.ai/api/scraper-api/api/scraper/group/[GROUP ID]/match/export/latest?format=jsonl&bucket=matched"
| Answer | Meaning |
|---|---|
200 | The file, gzip, for the group’s current run |
202 | The file is being built. Wait Retry-After seconds and ask again |
304 | You sent If-None-Match with the last ETag, and nothing changed |
404 | EXPORT_NO_MATCHED_RUN: the group has no finished run yet |
429 | EXPORT_DOWNLOAD_BUSY: too many downloads at once. Wait Retry-After |
- Is it ready?
GET .../match/export/latest/status(Read, free) or the MCP toolscrapewise_get_matched_export_latest_status(Read).ready: truemeans the file aturlis complete. - Keep it ready.
PUT .../match/export/auto(Full) with{"enabled":true,"formats":["jsonl"],"bucket":"matched"}builds a new file after each run and after review decisions.GET .../match/export/auto(Read) reads the setting. - A one-off file with your own filters: see Exports and delivery.
Errors you may see
Questions
Does a scheduled run cost money?
Yes, the same as a run you start by hand. It is charged to the group owner’s wallet. When the balance is too low, that run is skipped and shows in History.
Does changing the schedule start a run?
No. Only Save and run (with Run once) or Run match start a run.
What does Held mean?
The result looked wrong in size, for example far fewer rows than before. It was not delivered and your current results stay as they are.
Can I see what setup an old run used?
Yes. In Match quality, open Settings used for this run. Over the API, each history row carries the setup that run used.
Everything on this screen
Daily file:
- Keep a daily file ready: a switch in the export window. When on, a matched file is built each day so it is ready when you need it.
Last updated 4 November 2026